Modal alternatives
12 products compared · Updated November 2, 2026
The short answer
For teams deploying autonomous agents, Aden offers purpose-built infrastructure with deterministic execution and audit trails. Anthropic suits teams that want to use Claude models directly without managing infrastructure. Hugging Face is best for teams that want to host, share, and deploy open models with minimal setup.
Your shortlist, at a glance
Read the comparisons ↓ RunPodNot publishedTeams that need flexible GPU access across many regions and want to choose between persistent Pods and Serverless endpoints.
- RReplicateFrom $0.0001/secTeams that want to run or fine-tune open-source AI models via API without deep infrastructure expertise.
- TTogether AIFrom $1.40/M tokensTeams that want to run open-source models quickly with serverless inference or dedicated GPU capacity, without managing infrastructure.
- BBasetenNot publishedAI teams that need a managed inference platform with pre-optimized model APIs and the ability to self-host in their own cloud.
- AAnyscaleFrom $0.0135/hrTeams already using Ray or needing distributed training and data pipelines with multi-cloud GPU pooling and BYOC deployment.
 CoreWeaveCustom quoteAI teams running large-scale training or inference workloads that need dedicated GPU clusters and committed capacity.
 AdenFrom $20/mo for 500 crTeams deploying autonomous agents for business processes that need deterministic execution and audit trails.
 ConductorSee websiteRun a team of coding agents on your Mac
- PPoplarMLSee websiteDeploy Machine Learning Models with One Command
 TelnyxFrom $0.13/1M tokensTeams building voice AI agents or contact center applications that need carrier-grade telephony, edge compute, and GPU inference from a single vendor.
- TTensorPoolSee websiteVercel For GPUs
- TTensorfuseSee websiteRun serverless GPUs on your own cloud
About Modal and its alternatives
Modal is a cloud infrastructure platform for teams that develop, train, and serve AI applications at scale. It is known for serverless compute, per-second GPU billing, and primitives like Functions, Sandboxes, and Servers.
When comparing alternatives, weigh pricing structure (per-second vs per-hour vs per-token), global regions, integrations with existing tools, support quality, and contract terms like committed spend or minimums. Each product has different strengths, so match the platform to your workload type.
Explore the alternatives
- Not published
1.RunPod
Best for: Teams that need flexible GPU access across many regions and want to choose between persistent Pods and Serverless endpoints.
- Pricing
- Not published
- Category
- AI & Machine Learning
RunPod is a GPU cloud platform that offers Pods for persistent instances, Serverless for autoscaling inference, and Clusters for multi-node training. Choose it over Modal when you want a broader range of GPU SKUs, more global regions, and a simpler pay-as-you-go model without Modal's serverless function abstraction.
Where it is strong
- Supports over 30 GPU SKUs across 31 global regions.
- Serverless endpoints scale from 0 to thousands of workers in under 250ms.
- FlashBoot provides sub-200ms cold starts for inference.
Where it falls short
- Pricing details are not transparently listed on the site.
- Lacks Modal's built-in primitives like Sandboxes and Functions for complex AI workflows.
- Pricing:
- Pricing is not published on the site. It varies by GPU and workload type, with storage starting at $0.05/GB/mo.
- Switching from Modal:
- Moving from Modal to RunPod means rearchitecting your workloads to fit RunPod's Pods, Serverless, and Clusters model, rather than using Modal's function-based serverless compute.
- RFrom $0.0001/sec
2.Replicate
Best for: Teams that want to run or fine-tune open-source AI models via API without deep infrastructure expertise.
- Pricing
- From $0.0001/sec
- Category
- Other
Replicate is a cloud API for running and fine-tuning open-source machine learning models with a single line of code. You would choose it over Modal when you want to quickly use pre-built models without managing infrastructure, and you prefer a simpler, model-focused workflow.
Where it is strong
- Thousands of pre-built models ready to run with one line of code.
- Fine-tune models with your own data, or deploy custom models using Cog.
- Automatic scaling to zero when idle, so you only pay for active compute.
Where it falls short
- Less control over infrastructure and scheduling compared to Modal's primitives.
- Private models run on dedicated hardware, billing for idle time unless fast-booting.
- Pricing:
- Pricing is usage-based: CPU at $0.000100/sec, Nvidia T4 at $0.000225/sec, Nvidia L40S at $0.000975/sec, Nvidia A100 (80GB) at $0.001400/sec, and Nvidia H100 at $0.001525/sec.
- TFrom $1.40/M tokens
3.Together AI
Best for: Teams that want to run open-source models quickly with serverless inference or dedicated GPU capacity, without managing infrastructure.
- Pricing
- From $1.40/M tokens
- Category
- Other
Together AI is a full-stack AI cloud focused on running open-source models, with serverless inference, dedicated GPU clusters, and fine-tuning. You would choose it over Modal if you want a managed platform specifically for model inference and training with pre-optimized open models, rather than building custom infrastructure on Modal's primitives.
Where it is strong
- Optimized open-source models with fast inference
- Flexible options: serverless, batch, provisioned, dedicated
- GPU clusters with on-demand and reserved pricing
Where it falls short
- Pricing is per token, not per compute second, so costs vary by model
- Less flexible for custom code beyond model inference compared to Modal
- Pricing:
- Serverless inference is priced per 1M tokens, e.g., GLM-5.3 at $1.40 input and $4.40 output. Dedicated H100 GPUs at $5.49 per GPU per hour on-demand.
- BNot published
4.Baseten
Best for: AI teams that need a managed inference platform with pre-optimized model APIs and the ability to self-host in their own cloud.
- Pricing
- Not published
- Category
- Other
Baseten is a dedicated inference platform for serving open-source, custom, and fine-tuned AI models in production. Choose it over Modal when your focus is purely on high-performance inference with pre-optimized model APIs and the option to self-host in your own VPC.
Where it is strong
- Pre-optimized model APIs for instant testing and deployment
- Self-hosted deployment option in your own VPC
- SOC 2 Type II certified and HIPAA compliant
Where it falls short
- Pricing not published, requires contacting sales for details
- No sandboxes for running untrusted code or agents
- Pricing:
- Pricing is not published on the site.
- AFrom $0.0135/hr
5.Anyscale
Best for: Teams already using Ray or needing distributed training and data pipelines with multi-cloud GPU pooling and BYOC deployment.
- Pricing
- From $0.0135/hr
- Category
- Other
Anyscale is a managed platform built on Ray for running distributed data-intensive AI workloads like multimodal data curation, distributed training, and batch embedding generation. Choose it over Modal when you need fine-grained control over Ray clusters, multi-cloud orchestration, or want to use existing GPU reservations across clouds.
Where it is strong
- Built on Ray, the widely adopted AI compute engine
- Supports BYOC and on-prem deployment with existing GPU reservations
- Multi-cloud orchestration across AWS, GCP, Azure, Nebius, CoreWeave
Where it falls short
- Limited regions for hosted deployment compared to Modal's global reach
- No serverless function primitives like Modal's API gateways or sandboxes
- Pricing:
- Pricing is usage-based with no monthly fixed fees. Compute costs start at $0.0135/hr for CPU-only instances, $0.5682/hr for NVIDIA T4, and $4.9591/hr for NVIDIA A100.
- Custom quote
6.CoreWeave
Best for: AI teams running large-scale training or inference workloads that need dedicated GPU clusters and committed capacity.
- Pricing
- Custom quote
- Category
- AI & Machine Learning
CoreWeave is a specialized AI cloud offering GPU compute, storage, and networking for large-scale training and inference. Choose it over Modal when you need dedicated, high-performance infrastructure with reserved capacity and direct access to experts, rather than serverless functions and autoscaling.
Where it is strong
- Dedicated GPU clusters for large-scale training and inference
- Up to 60% discounts for committed usage
- Direct access to experts, no non-technical layer
Where it falls short
- No serverless or autoscaling model. You manage capacity
- Pricing not transparent. Requires contacting sales
- Pricing:
- Pricing is not published on the site. Only a note that committed usage can get up to 60% discounts over on-demand prices.
- Switching from Modal:
- Moving from Modal means shifting from serverless functions to managing dedicated GPU instances, which requires rearchitecting your workload deployment.
- From $20/mo for 500 cr
7.Aden
Best for: Teams deploying autonomous agents for business processes that need deterministic execution and audit trails.
- Pricing
- From $20/mo for 500 cr
- Category
- AI & Machine Learning
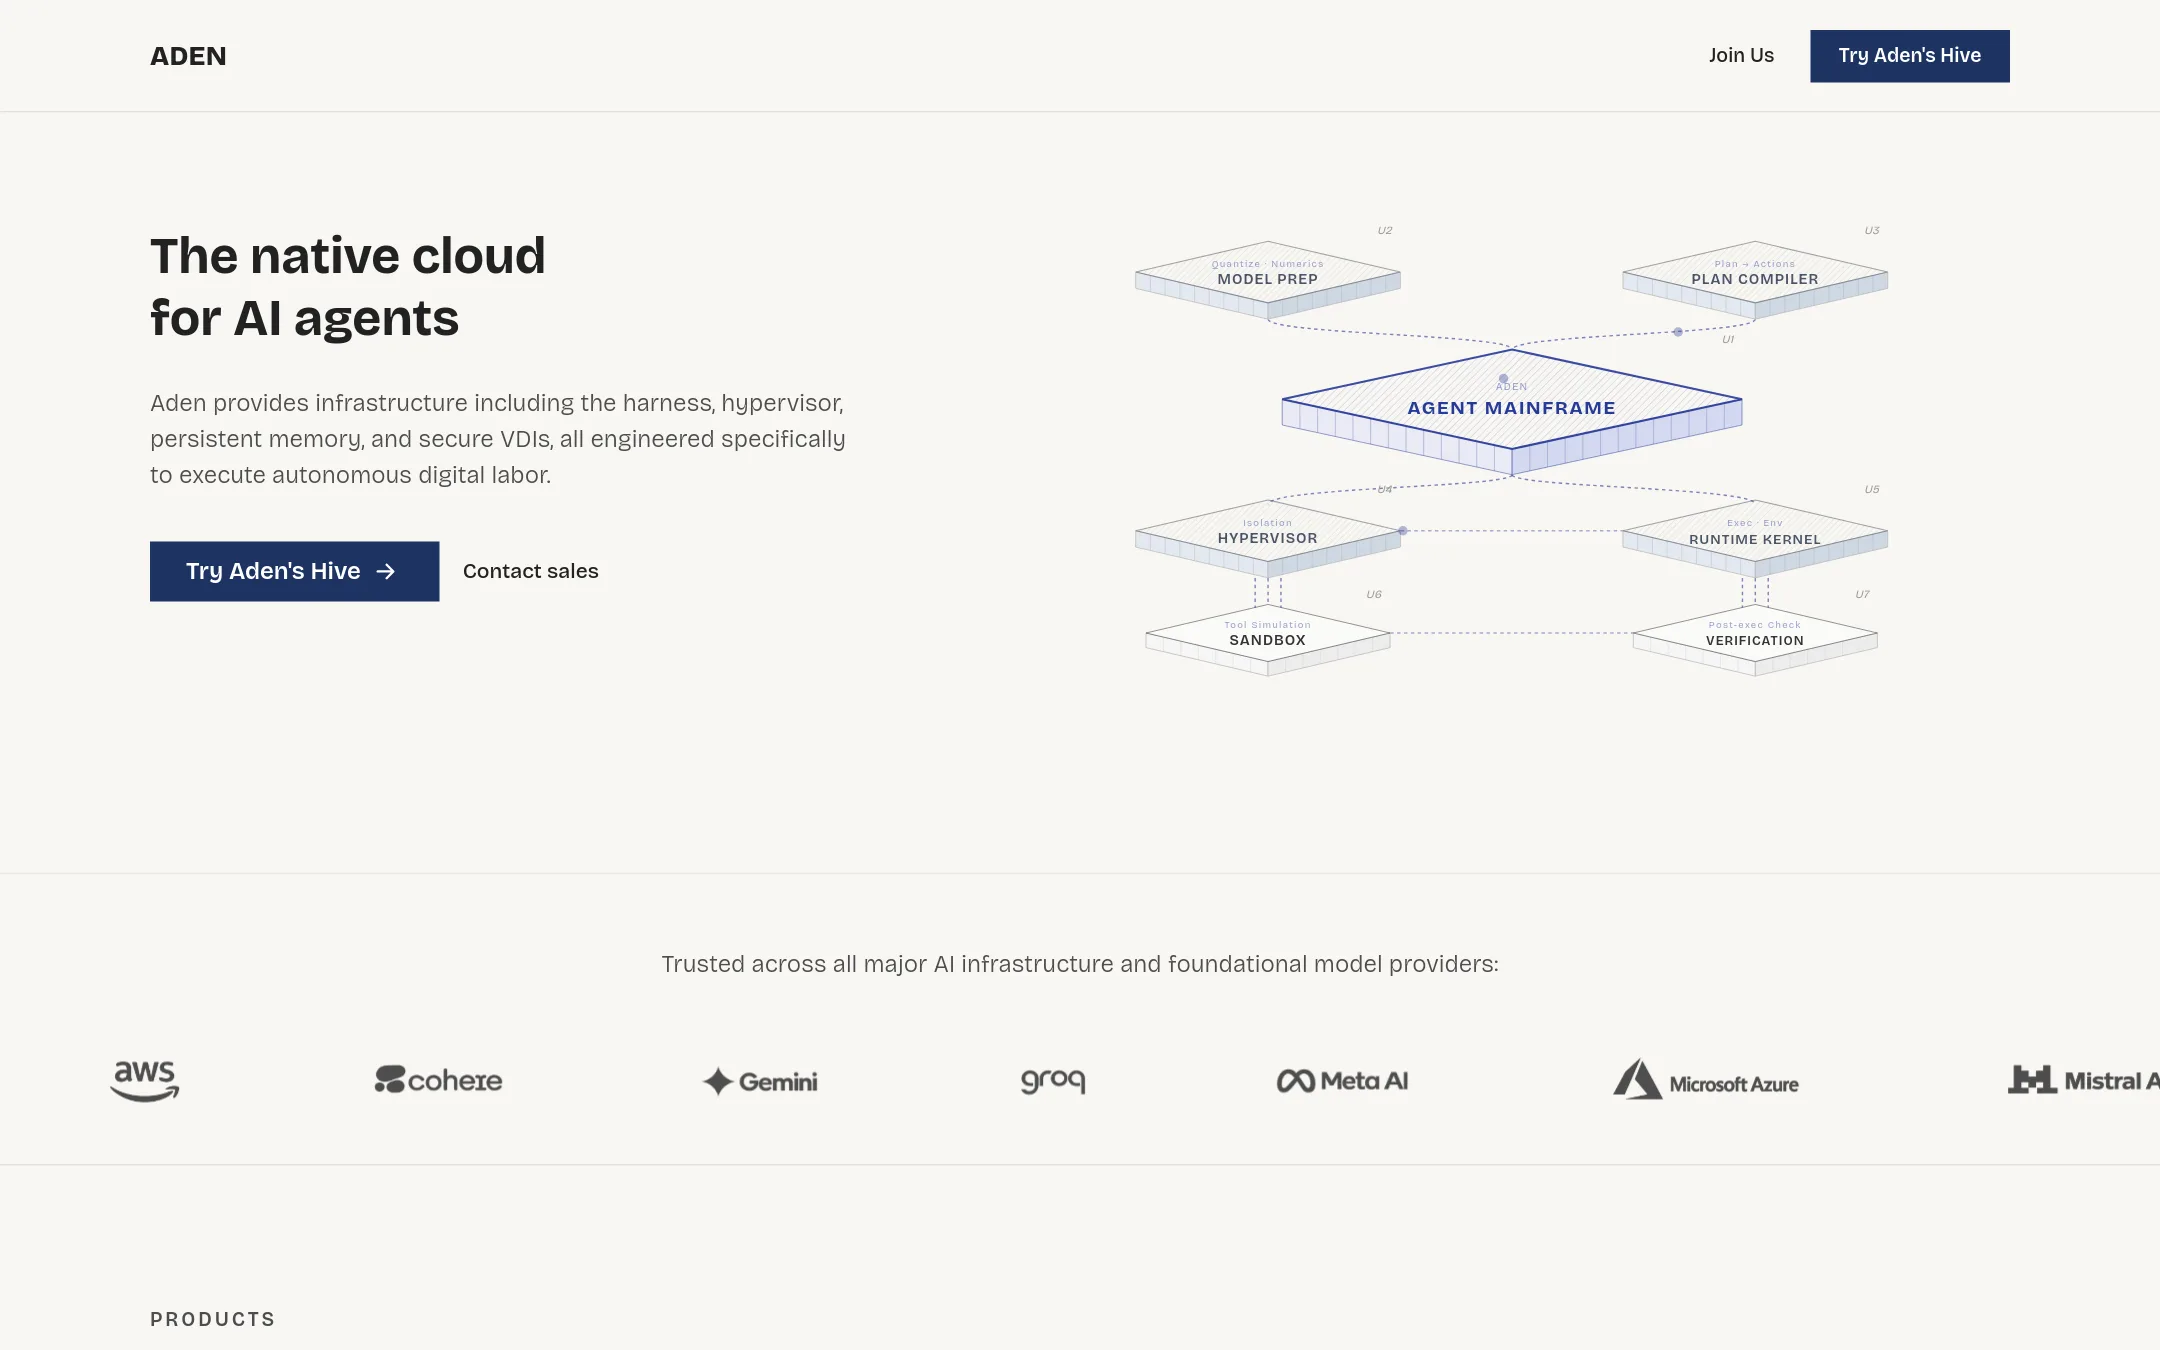
Aden is infrastructure built specifically for running autonomous AI agents as digital labor, with a hypervisor, persistent memory, and secure VDIs. Choose it over Modal when your focus is on deploying repeatable business workflows and agent teams, rather than training or serving AI models at scale.
Where it is strong
- Purpose-built for autonomous agent workloads with hypervisor isolation.
- Includes persistent memory and secure VDIs for agent execution.
- Offers an open-source agent framework (OpenHive) and a job index (Honeycomb).
Where it falls short
- Pricing is credit-based, which may be less predictable than compute-time billing.
- No mention of GPU-specific pricing or training capabilities, unlike Modal's per-second GPU rates.
- Pricing:
- Credits start at 500 per month for $20, with higher tiers up to 20,000 credits for $200. Custom volume pricing is available.
- See website
8.Conductor
Developer Tools
Run a team of coding agents on your Mac
- PSee website
9.PoplarML
AI & Machine Learning
Deploy Machine Learning Models with One Command
- From $0.13/1M tokens
10.Telnyx
Best for: Teams building voice AI agents or contact center applications that need carrier-grade telephony, edge compute, and GPU inference from a single vendor.
- Pricing
- From $0.13/1M tokens
- Category
- Communication & Collaboration
Telnyx is a licensed carrier that also runs its own GPU inference and edge compute, so you can build voice AI agents and keep the network, model serving, and application runtime under one contract. Choose it over Modal when you need real-time voice or communications features alongside inference, and you want to avoid stitching together separate providers.
Where it is strong
- Owns the carrier network, GPUs, and edge compute, so latency and compliance are under one roof.
- Usage-based pricing published for every product, with no minimum on pay-as-you-go.
- OpenAI-compatible inference API, so you can switch from OpenAI SDK with just a base URL change.
Where it falls short
- Focus is on communications and voice AI, so it lacks Modal's broader training and batch job orchestration features.
- Growth and Enterprise plans require high monthly minimums ($2,000 and $5,000), which may be steep for small teams.
- Pricing:
- Inference starts at $0.130 per 1M tokens, voice AI agents from $0.05 per minute, SIP trunking from $0.0032 per minute, and numbers from $1 per month. Pay-as-you-go has no minimum. Growth requires $2,000/month minimum. Enterprise requires $5,000/month minimum.
- Switching from Modal:
- Moving from Modal means adapting your code to Telnyx's edge compute and inference APIs, and likely reworking any training or batch workloads that Modal handles.
- TSee website
11.TensorPool
AI & Machine Learning
Vercel For GPUs
- TSee website
12.Tensorfuse
AI & Machine Learning
Run serverless GPUs on your own cloud
See more comparisons in AI & Machine Learning alternatives.
FAQ
Questions about Modal alternatives
What is the main difference between Modal and Aden?
Modal is general-purpose AI infrastructure for training and inference, while Aden is built specifically for running autonomous agents as digital labor. Choose Aden if your focus is on business process automation, not model training.
Which alternative is best for teams that want to use pre-built models?
Hugging Face and Replicate are strong choices. Hugging Face offers a hub of 45,000+ models with minimal setup, while Replicate lets you run open-source models with one line of code. Both avoid deep infrastructure management.
How do pricing models compare across these alternatives?
Modal bills per second of compute, while Hugging Face and RunPod charge per hour. Together AI and Telnyx price per token or per minute. Aden uses credits, and some like Baseten and CoreWeave do not publish pricing. Choose based on your workload's predictability.
Which alternatives support large-scale training?
CoreWeave and Anyscale are designed for large-scale training. CoreWeave offers dedicated GPU clusters with committed capacity, while Anyscale provides distributed training on Ray with multi-cloud orchestration. Both require more hands-on management than Modal.
Are there alternatives that offer voice AI or communications features?
Telnyx is unique in combining carrier-grade telephony, edge compute, and GPU inference. It is ideal for building voice AI agents or contact center applications, with published usage-based pricing and no minimum on pay-as-you-go.
Last updated November 2, 2026.