Chunkr alternatives
6 products compared · Updated November 11, 2026
The short answer
The three strongest Chunkr alternatives are Reducto, LlamaParse (from LlamaIndex) and Unstructured. Reducto suits AI teams processing table-heavy financial or legal documents that need bounding-box citations. LlamaParse suits enterprise teams in finance, insurance and healthcare that need table, chart and handwriting parsing plus schema-based extraction in one platform. Unstructured suits enterprise teams in finance, healthcare, legal or insurance that need to process mixed document types from many sources into a vector database.
Your shortlist, at a glance
Read the comparisons ↓ LlamaIndexNot publishedEnterprise teams in finance, insurance and healthcare that need table, chart and handwriting parsing plus schema-based extraction in one platform
- UUnstructured$0.015/page after 10k Enterprise teams in finance, healthcare, legal or insurance that need to process mixed document types from many sources into a vector database.
- RReductoFrom $1 / 1,000 pagesAI teams processing table-heavy financial or legal documents that need bounding-box citations
 Argo CDNot publishedPlatform and DevOps teams running Kubernetes who want Git-based deployments with a visual dashboard
- MMistral AIFrom $14.99/moRegulated enterprises in energy, finance and the public sector that need to run AI models on their own infrastructure.
Microsoft Azure CycleCloudCustom quoteEngineering teams running HPC or batch compute workloads on Azure that need cluster management
About Chunkr and its alternatives
Chunkr is an open source API service that parses complex documents such as PDFs, images and spreadsheets into LLM-ready HTML, Markdown or JSON. According to its site, it is known for OCR, layout detection, reading order, bounding boxes, citations and schema-based extraction, with a three-line SDK integration in TypeScript or Python.
When comparing alternatives in this category, weigh the pricing structure first, since some tools charge per page, per credit or per seat, and some publish no prices at all. Check which regions and data residency options are offered, which integrations exist with your storage and vector database, how support works on each tier, and what the contract terms and deployment options (cloud, VPC or on-prem) look like for your data.
Explore the alternatives
- Not published
1.LlamaIndex
Best for: Enterprise teams in finance, insurance and healthcare that need table, chart and handwriting parsing plus schema-based extraction in one platform
- Pricing
- Not published
- Category
- AI & Machine Learning
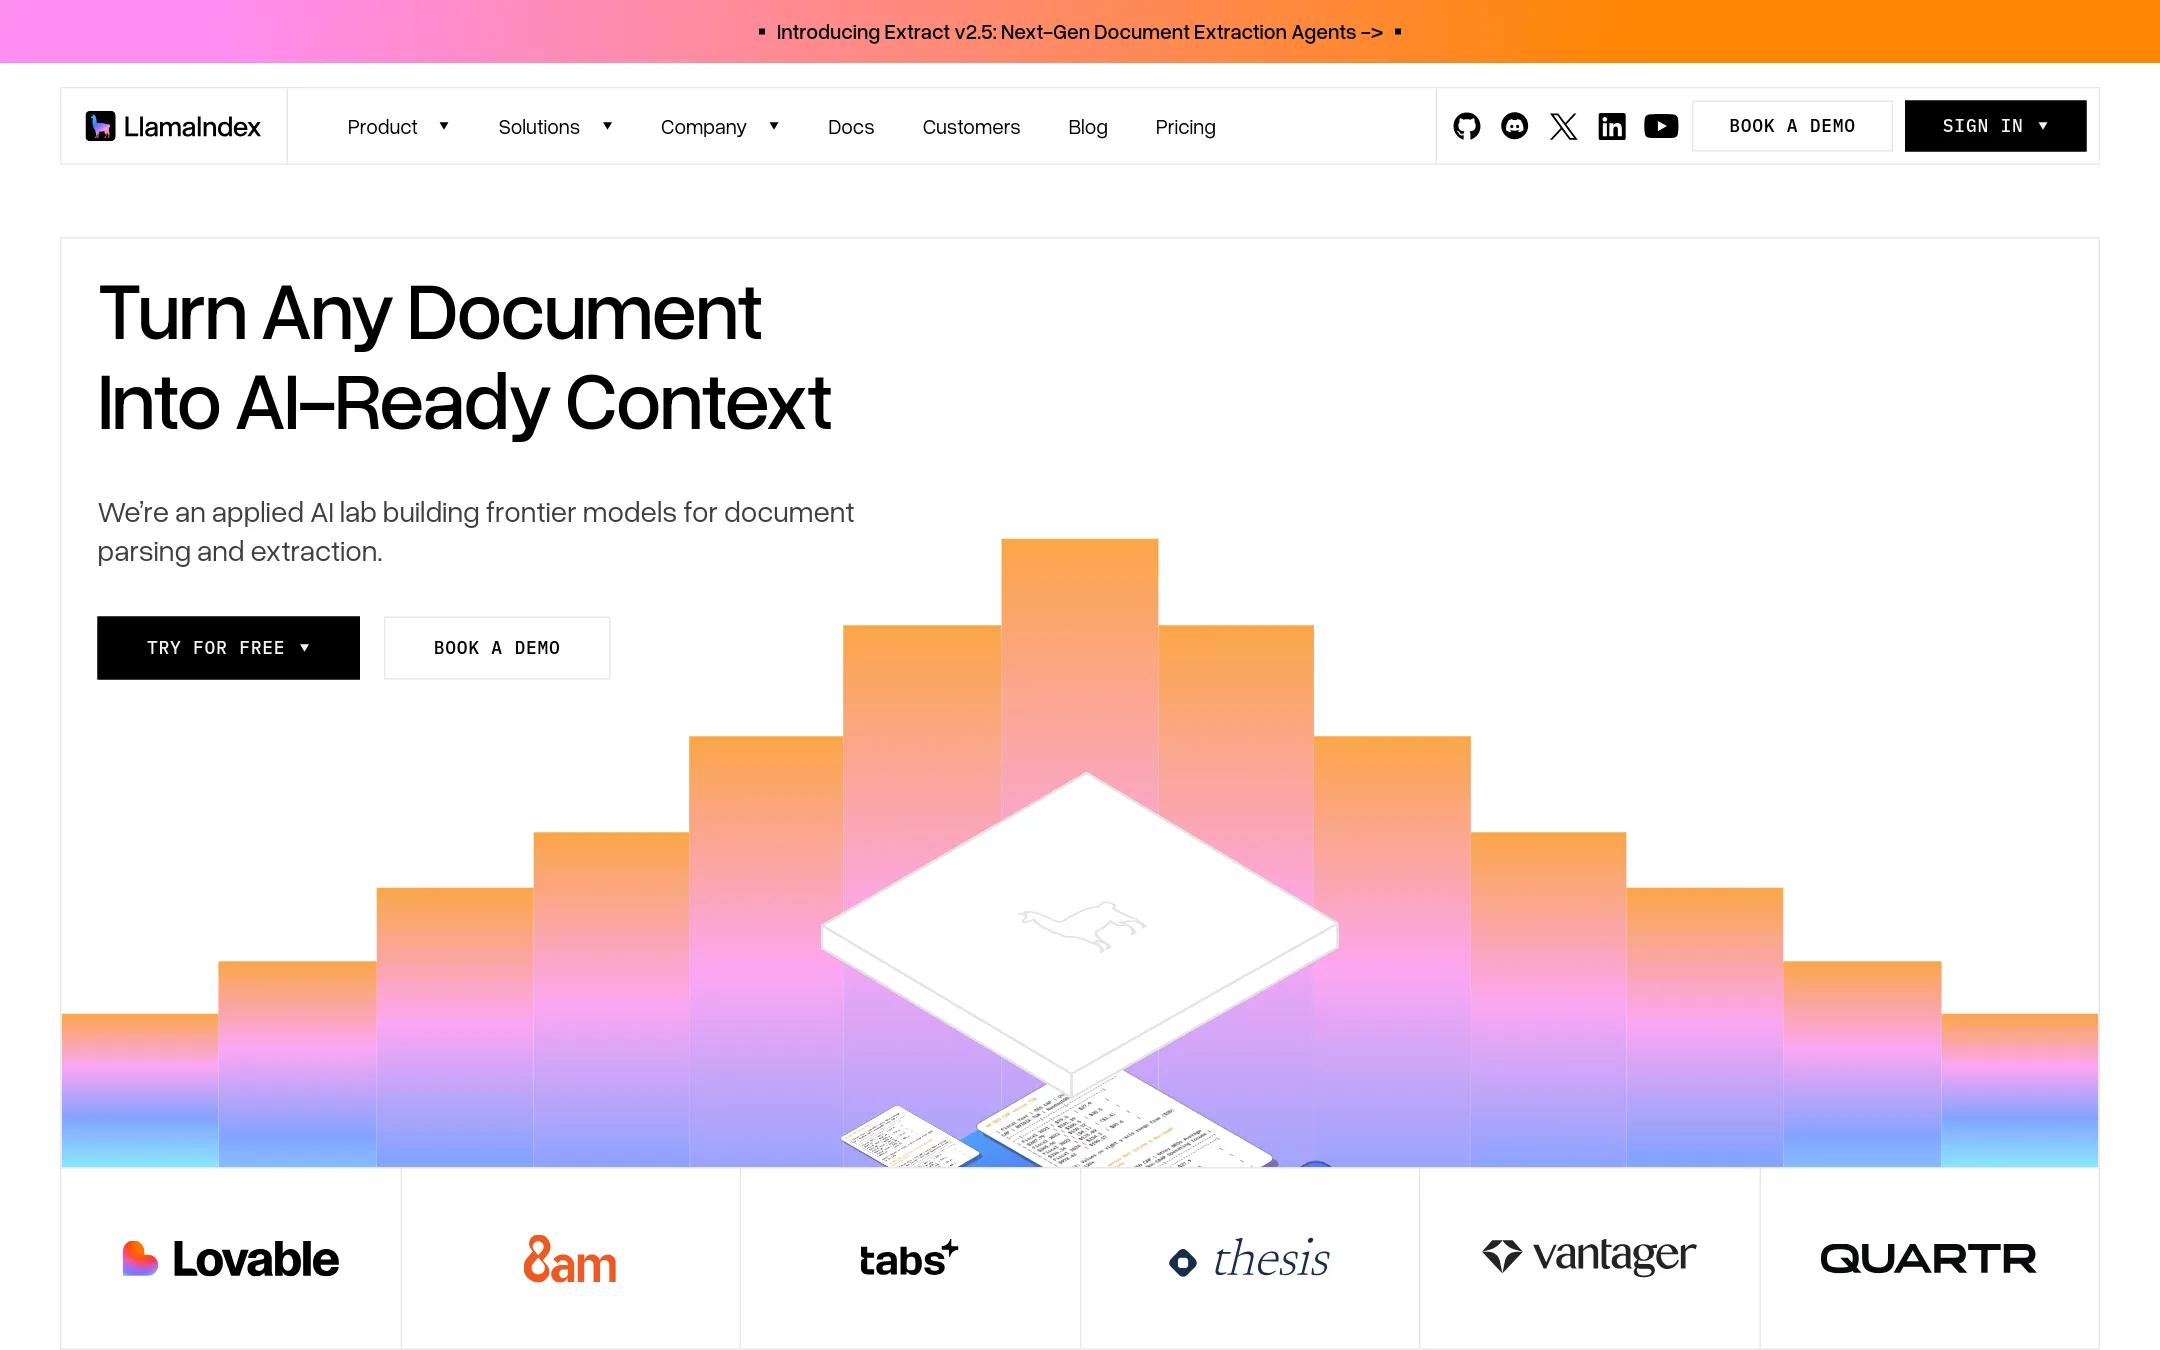
LlamaParse is a hosted document parsing and extraction platform. It turns PDFs, Office files, spreadsheets and images into LLM-ready markdown or JSON, with table and chart extraction, schema-based extraction agents, and handwriting support. Teams pick it over Chunkr when they need that broader set of extraction, classification and indexing tools in one platform.
Where it is strong
- Handles tables, charts and handwritten notes, not just plain text
- Offers schema-based extraction, classification and splitting alongside parsing
- Lists SOC2, HIPAA and GDPR compliance and VPC deployment for regulated teams
Where it falls short
- LlamaParse is a commercial platform and is not open source, unlike Chunkr
- Credit-based billing makes monthly cost harder to predict, since cost varies by parsing mode
- Pricing:
- Pricing is not published on the site.
- U$0.015/page after 10k
2.Unstructured
Best for: Enterprise teams in finance, healthcare, legal or insurance that need to process mixed document types from many sources into a vector database.
- Pricing
- $0.015/page after 10k
- Category
- Other
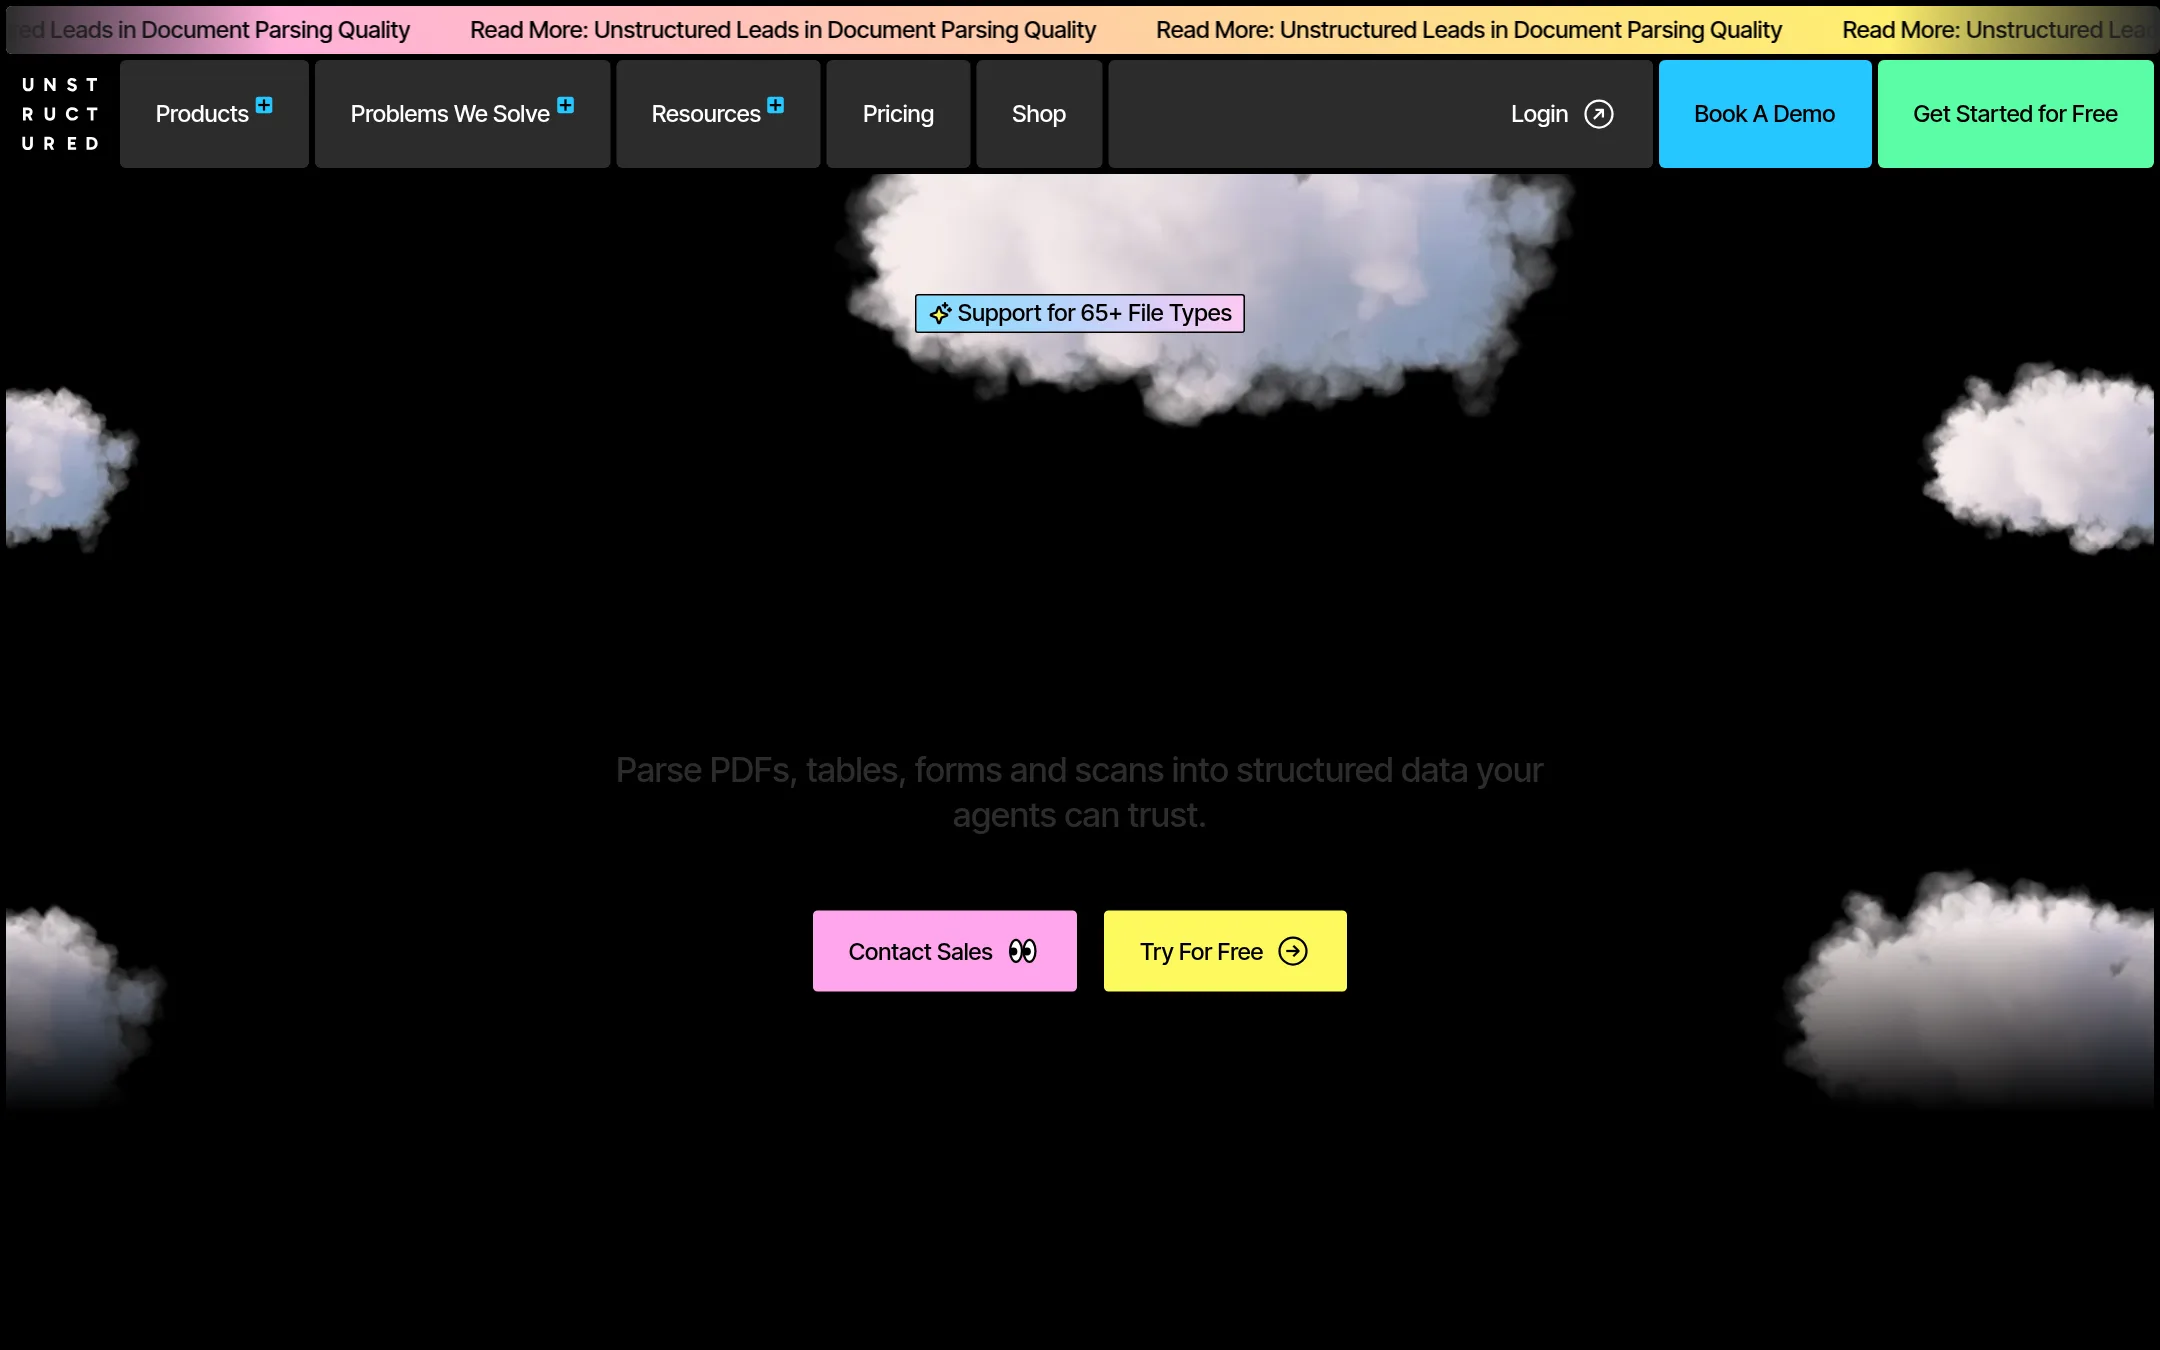
Unstructured turns PDFs, Word and Excel files, emails, HTML, images and scans into clean, structured data for RAG pipelines and AI agents. It covers the whole path, including connecting to sources like S3 and SharePoint and loading results into vector databases on a schedule. Choose it over Chunkr when you need that connect-to-load pipeline across 50+ file types, or when you need deployment in your own VPC for regulated data.
Where it is strong
- Handles 50+ file types, including Word, Excel, email and scans, through one pipeline.
- Connects to 20+ sources and 20+ destinations, including major vector databases.
- Offers SOC 2 Type 2, HIPAA, GDPR, ISO 27001 and FedRAMP High options, with in-VPC deployment.
Where it falls short
- Pay-as-you-go starts at $0.015 per page after the free tier, and enterprise pricing requires a quote.
- The site describes it as an enterprise-oriented product, so the self-serve path is less visible than the Business plan.
- Pricing:
- Pricing is not published on the site as a full schedule. The page lists 10,000 free pages, then $0.015 per page on pay-as-you-go, and custom pricing for Business plans.
- Switching from Chunkr:
- Moving from Chunkr would mean replacing its parsing API with Unstructured's pipeline, which connects to sources and destinations. The site does not describe a migration path.
- RFrom $1 / 1,000 pages
3.Reducto
Best for: AI teams processing table-heavy financial or legal documents that need bounding-box citations
- Pricing
- From $1 / 1,000 pages
- Category
- AI & Machine Learning
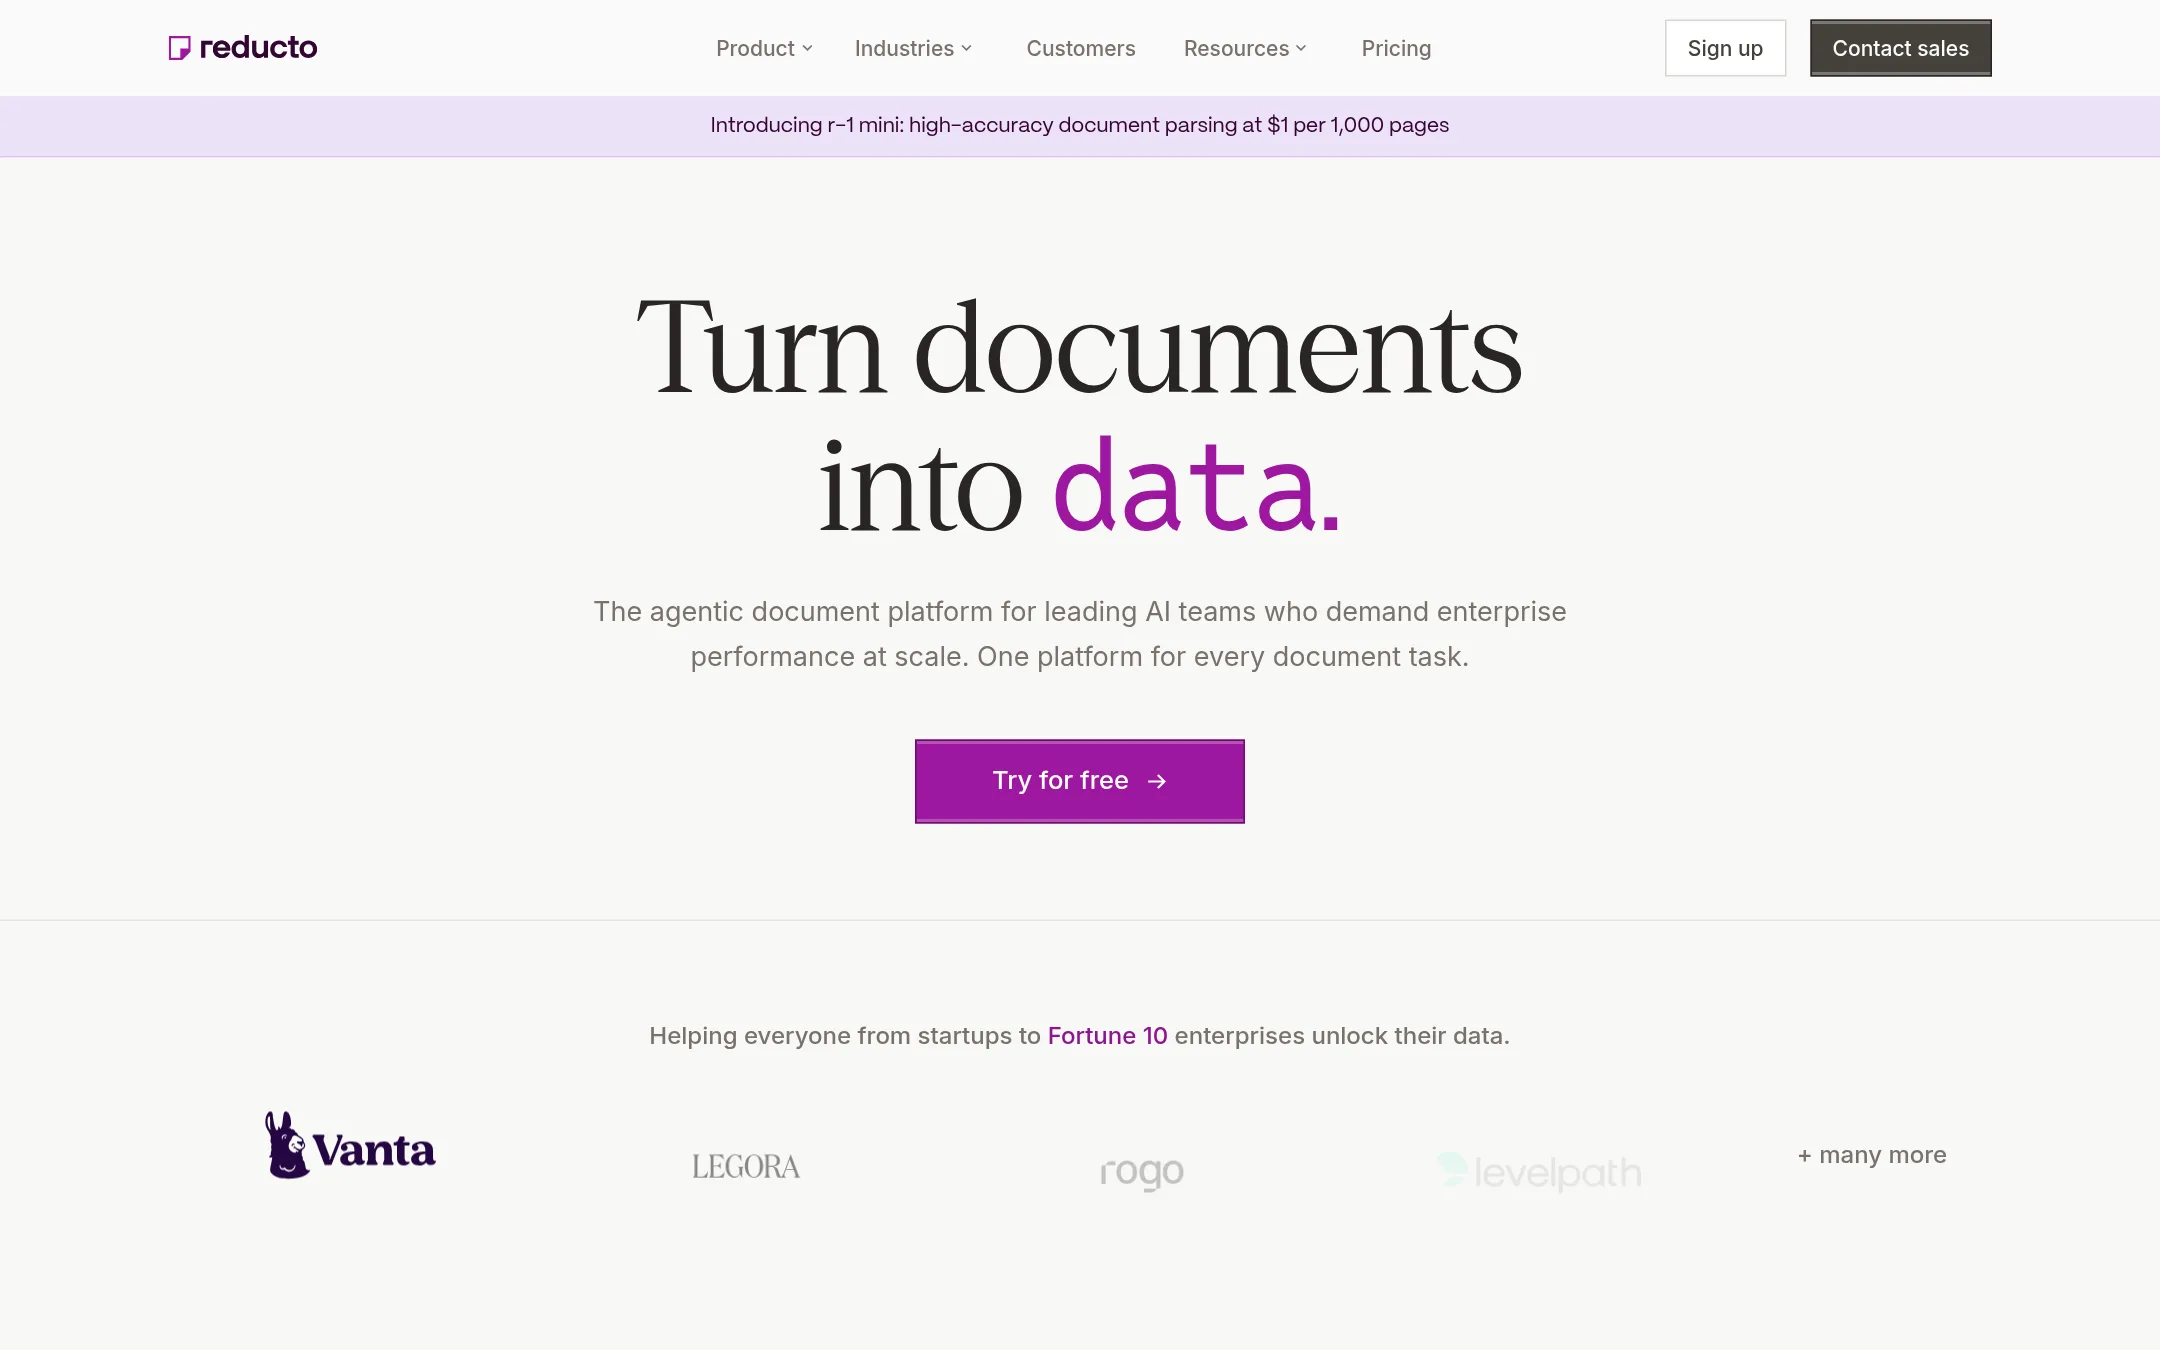
Reducto is a document API that parses PDFs, images, spreadsheets and more into structured output, with bounding-box citations, schema-based extraction, splitting and form filling. Teams choose it over Chunkr when table-heavy or messy documents are the core problem, or when they need separate endpoints for parse, extract, split and edit. It also offers EU and AU data residency endpoints and VPC or on-prem deployment on its enterprise tier.
Where it is strong
- Handles complex tables, forms, charts and equations with bounding-box citations
- Separate Parse, Extract, Split and Edit endpoints for distinct document tasks
- Supports over 30 file types and offers EU and AU data residency endpoints
Where it falls short
- Costs rise quickly on the full r-1 model and on Edit, compared with cheaper tiers
- Custom deployment, SSO and dedicated support sit behind enterprise pricing rather than a self-serve plan
- Pricing:
- Pricing is published with list rates per 1,000 pages: r-1 Parse at $10, r-1 mini Parse at $1, Extract at $20, Deep Extract at $40, Split at $10, Classify at $7.50 and Edit at $60, with startup credits and volume discounts available on higher tiers.
- Not published
4.Argo CD
Best for: Platform and DevOps teams running Kubernetes who want Git-based deployments with a visual dashboard
- Pricing
- Not published
- Category
- Developer Tools
Argo CD is an open source tool that runs continuous delivery for Kubernetes using GitOps, where the desired state of your apps lives in Git and the tool keeps the cluster in sync with it. It ships with a full web UI for watching deployments. Teams would pick it over Chunkr when their need is deploying and managing applications on Kubernetes rather than parsing documents.
Where it is strong
- Open source, with the source code available on the project site.
- Includes a fully-loaded UI for viewing and managing deployments.
- Part of a wider Argo suite that also covers workflows, rollouts and events.
Where it falls short
- It solves deployment and delivery, so it does not parse documents or extract data at all.
- It is built for Kubernetes, so teams not running clusters have no use for it.
- Pricing:
- Pricing is not published on the site.
- MFrom $14.99/mo
5.Mistral AI
Best for: Regulated enterprises in energy, finance and the public sector that need to run AI models on their own infrastructure.
- Pricing
- From $14.99/mo
- Category
- Other
Mistral AI is a model and software company whose main pitch is sovereign AI: open-weight models that a company can customize with Forge, build agents on with Studio, and run on-prem, in a VPC, or on Mistral cloud. Someone would pick it over Chunkr if the goal is a general-purpose model and agent platform that keeps data and inference under their control, rather than a document parsing API.
Where it is strong
- Open-weight models that customers can keep and tailor to their own data
- Deployment options on-prem, in a VPC, or on Mistral cloud with in-region inference
- Named customers across energy, manufacturing, finance and government
Where it falls short
- Parsing complex documents into HTML, Markdown or JSON with bounding boxes is not described as a core feature the way it is with Chunkr
- Enterprise pricing requires contacting sales, so costs at scale are not published
- Pricing:
- The pricing page lists a free tier, a Pro plan at $14.99 per month, a Team plan at $24.99 per user per month, and a custom-quoted Enterprise plan, with prices shown in USD by default.
- Custom quote
6.Microsoft Azure CycleCloud
Best for: Engineering teams running HPC or batch compute workloads on Azure that need cluster management
- Pricing
- Custom quote
- Category
- Developer Tools
Azure CycleCloud is an orchestration tool for running and managing HPC and batch compute clusters on Azure. Someone would pick it over Chunkr when their need is scheduling large compute jobs across cloud infrastructure rather than parsing documents into structured data.
Where it is strong
- Manages HPC clusters on Azure infrastructure
- Sits inside the broader Azure platform and account
- Offers consumption-based pricing with commitment discounts
Where it falls short
- Does not parse documents or extract data, so it is not a substitute for Chunkr
- Pricing depends on underlying Azure resource usage, which takes work to estimate
- Pricing:
- In the United States, Azure pricing is consumption-based with options such as reservations and savings plans, but the page shows no concrete figures for CycleCloud itself.
- Switching from Chunkr:
- Moving from Chunkr to CycleCloud would mean replacing a document parsing API with a cluster orchestration tool, so it is a change of purpose rather than a like-for-like swap.
See more comparisons in Developer Tools alternatives.
FAQ
Questions about Chunkr alternatives
What is the best alternative to Chunkr for table-heavy financial documents?
Reducto is the entry most aimed at this case. It handles complex tables, forms and charts with bounding-box citations and offers separate Parse, Extract and Split endpoints. Its r-1 model is the costlier option, so budget against the per-1,000-page list rates.
Which Chunkr alternative offers the most open or self-hosted deployment?
Unstructured offers in-VPC deployment for regulated data, and LlamaParse lists VPC deployment for regulated teams. Reducto offers VPC or on-prem deployment on its enterprise tier. Confirm the exact deployment terms with each vendor, since enterprise options usually require a quote.
Is there a Chunkr alternative with published pricing?
Reducto publishes list rates per 1,000 pages, and Unstructured lists 10,000 free pages followed by $0.015 per page on pay-as-you-go. Mistral AI publishes plan prices, though its enterprise plan is quoted by sales. Pricing for LlamaParse is not published on its site.
Which alternative is best for connecting document sources to a vector database?
Unstructured is built for that path. It connects to over 20 sources, such as S3 and SharePoint, and over 20 destinations including major vector databases, and it can run loads on a schedule. It also handles more than 50 file types through one pipeline.
Do any of these alternatives compete directly with Chunkr on document parsing?
Reducto, LlamaParse and Unstructured all parse documents into structured output for AI use. Azure CycleCloud and Argo CD do not parse documents, so they are not substitutes. Mistral AI is a model and agent platform, and its site does not describe document parsing with bounding boxes as a core feature.
Last updated November 11, 2026.